SilentPulse is not an AI company.
We don’t train models. We don’t sell API tokens. We don’t have a “proprietary AI engine” slide in our deck. We build software that monitors whether your security telemetry is actually flowing, and we’ve been doing that since day one.
That said, large language models offer real, practical value for security operations. Not the hype, but the kind of value that matters: taking a complex, multi-signal alert and turning it into a plain-language explanation that a SOC analyst can act on in seconds.
So we built it. Carefully, opinionatedly, and on your terms.
The problem: alert fatigue meets context overload
When SilentPulse detects that telemetry has gone silent for an asset, it generates an alert. That alert contains structured data: which asset, which flow stage failed, which security functions are affected, which MITRE ATT&CK techniques lost coverage, how long the gap has been open.
For an experienced detection engineer, that’s enough. They see “DC-PROD-01 silent on Kafka for 2 hours, Endpoint Security + Authentication degraded, 14 MITRE techniques affected” and they know exactly what to do.
But not every analyst has that depth. And even experienced analysts benefit from a second perspective when triaging at 3 AM during an incident. The data is all there, but the interpretation is missing.
That’s what our AI assistant provides: instant, contextual interpretation of alert data.
How it works
On the alert detail page, analysts see a “Generate AI Explanation” button. One click, and SilentPulse sends the alert’s structured context (asset details, flow stage, security function impact, MITRE techniques, timeline) to the configured LLM provider. The model returns three things:
Summary - A plain-language description of what happened and why it matters. Not a restatement of the alert fields, but an actual explanation: “Your primary domain controller has stopped sending Windows Security event logs to the Kafka pipeline. This means credential-based attacks against Active Directory, including Kerberoasting, DCSync, and lateral movement via remote services, are currently invisible to your detection stack.”
Impact assessment - What this silence means operationally. Which detection capabilities are degraded. How this affects the organization’s security posture. Whether this is a recurring pattern.
Remediation steps - Concrete, actionable next steps. Not generic advice, but recommendations informed by the specific alert context: check the Winlogbeat service on the host, verify Kafka topic connectivity, escalate to the infrastructure team if the agent is running but events aren’t arriving.
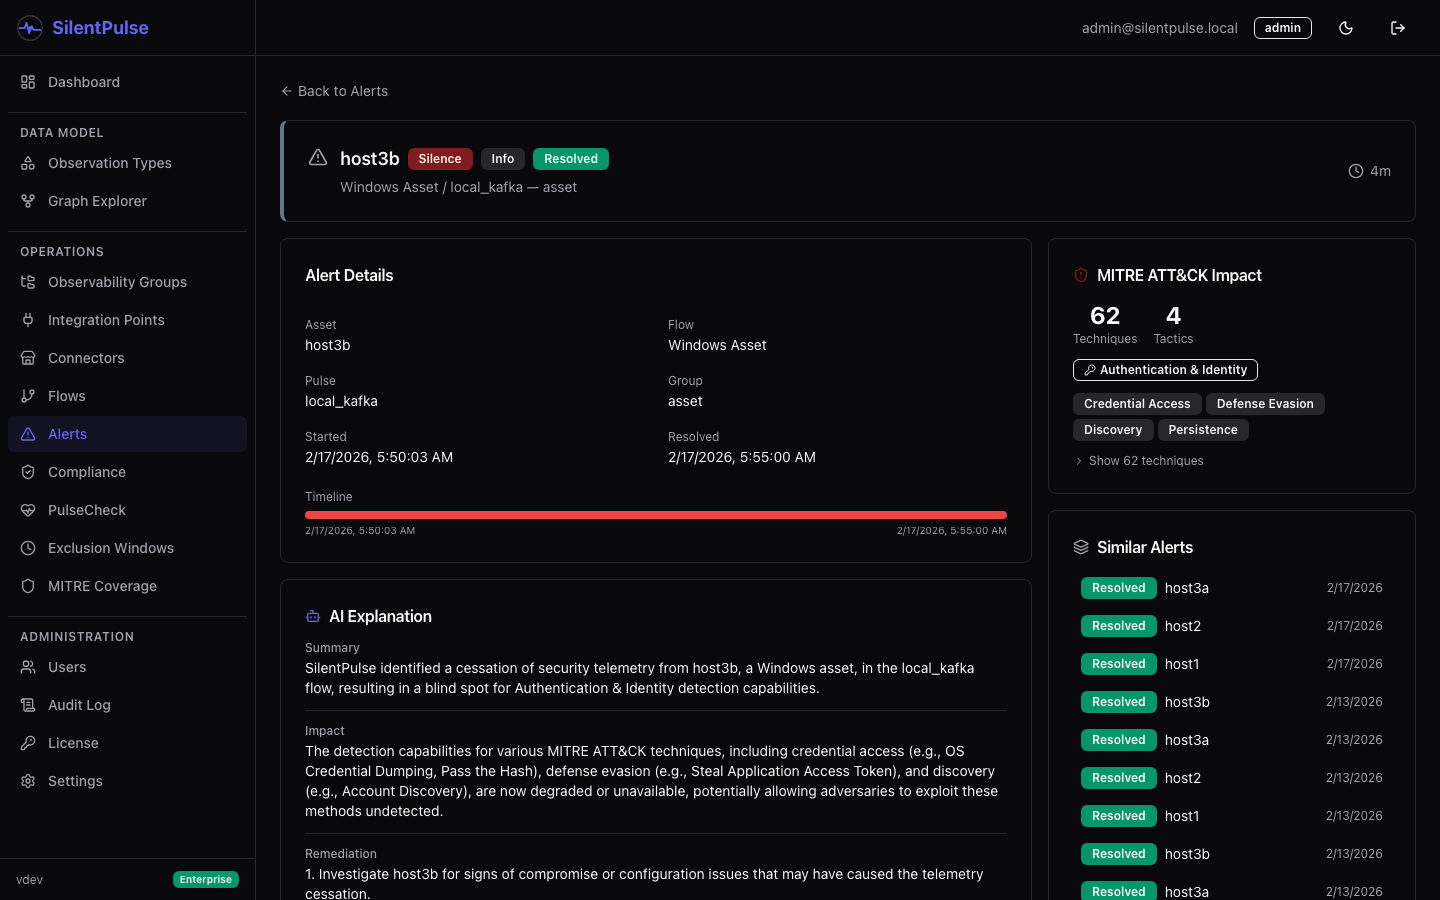
The explanation appears directly on the alert detail page, alongside MITRE ATT&CK impact data and similar alerts. Everything an analyst needs in one view, without switching tabs or tools.
BYO LLM: your model, your infrastructure, your rules
This is where we diverge from every “AI-powered security” product on the market.
SilentPulse doesn’t come with a built-in model. It doesn’t phone home to our API. It doesn’t send your alert data to a third-party cloud service (unless you choose to). Instead, it uses a Bring Your Own LLM architecture.
You configure which LLM provider to use. Currently supported:
- Ollama - Run models locally. Llama, Mistral, Mixtral, Qwen, whatever you prefer. Your data never leaves your network. Zero cost per query.
- OpenAI-compatible APIs - Any endpoint that speaks the OpenAI chat completions protocol. That includes OpenAI itself, Azure OpenAI, Databricks Foundation Model APIs, Together AI, Groq, vLLM, and dozens of others.
- Anthropic - Claude models via direct API.
The configuration is straightforward: provider type, endpoint URL, model name, API key (if needed). SilentPulse handles the rest, including prompt construction, response parsing, and caching.
Provider: Ollama
Endpoint: http://ollama:11434
Model: llama3.1:8b
API Key: (none needed)
This matters for three reasons:
Data sovereignty. Many organizations can’t send security alert data to external APIs. With Ollama or a self-hosted model, everything stays on-premises. The LLM runs in your Kubernetes cluster, on your hardware, under your control.
Cost control. No per-query pricing from us. If you run Ollama locally, the marginal cost of an explanation is effectively zero. If you use a cloud API, you pay the provider directly at their published rates.
Model choice. Different models have different strengths. A small, fast model like Llama 3.1 8B is great for quick explanations. A larger model like GPT-4 or Claude Opus might provide deeper analysis for complex multi-stage alerts. You choose based on your needs, and you can change your mind anytime.
The redesigned alerts experience
The AI assistant is part of a broader redesign of the alerts experience in SilentPulse.
Alerts dashboard
The alerts list page now opens with a stats bar. At a glance, you see how many alerts are open, acknowledged, and resolved, broken down by severity. A timeline chart shows alert volume over time, making patterns immediately visible: did alerts spike after a change window? Is there a recurring pattern on weekends?
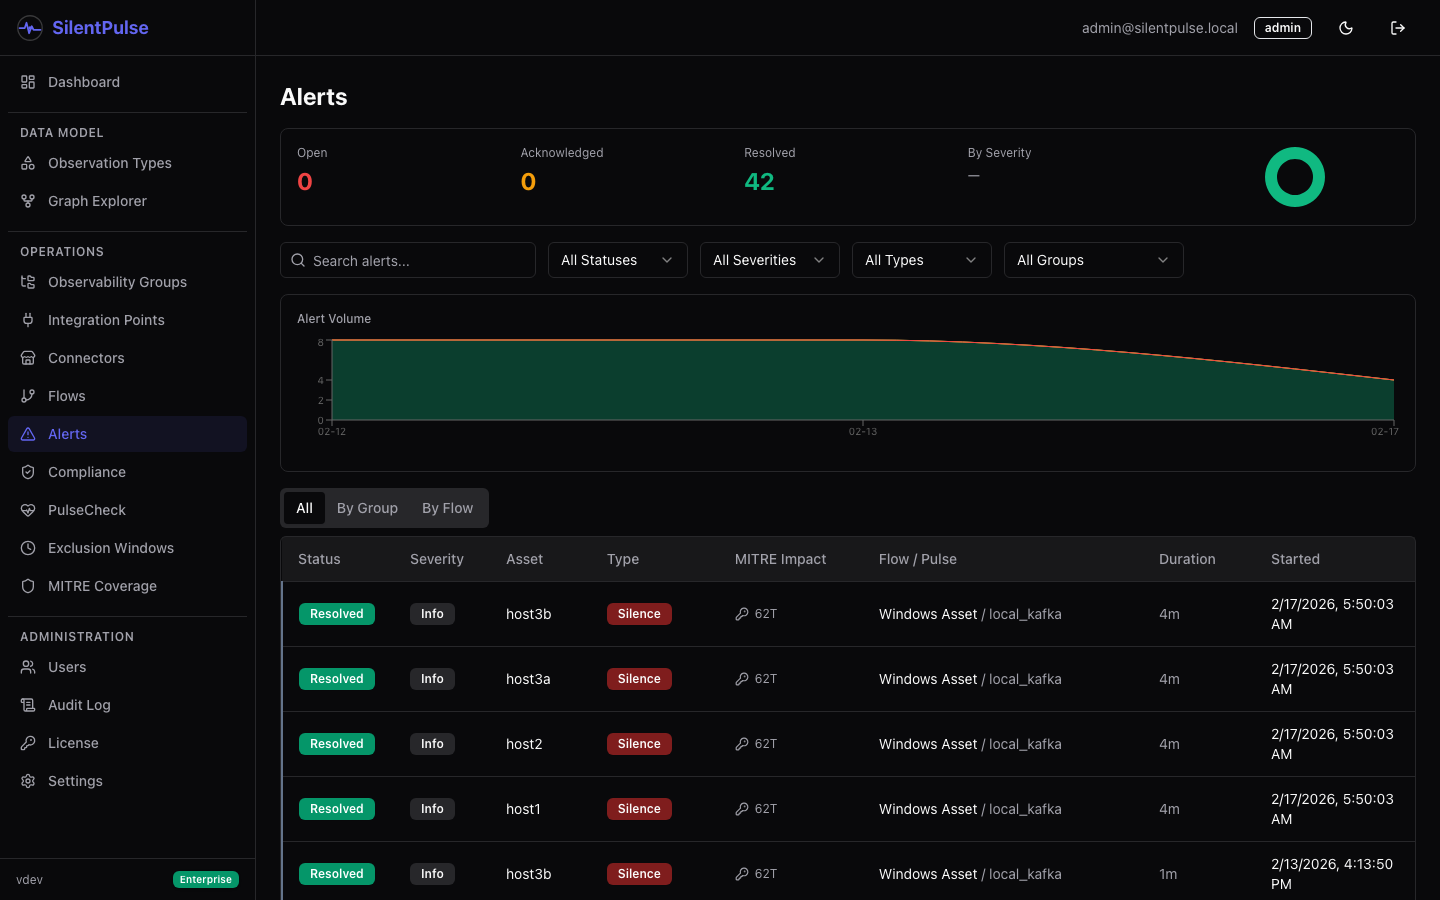
Search and filtering work across the entire alert corpus. Search by asset name, flow name, or pulse label. Filter by status, severity, alert type, or asset group. The filters compose naturally: “show me all critical silence alerts in the AD Production Servers group that are still open.”
Alert detail
Individual alert pages now use a full-width two-column layout. The left panel (two-thirds width) shows alert context, including asset, flow, pulse, timestamps, and a visual timeline bar showing the progression from open to acknowledged to resolved, followed by the AI explanation. The right panel shows MITRE ATT&CK impact (technique and tactic counts, expandable technique table) and similar alerts.
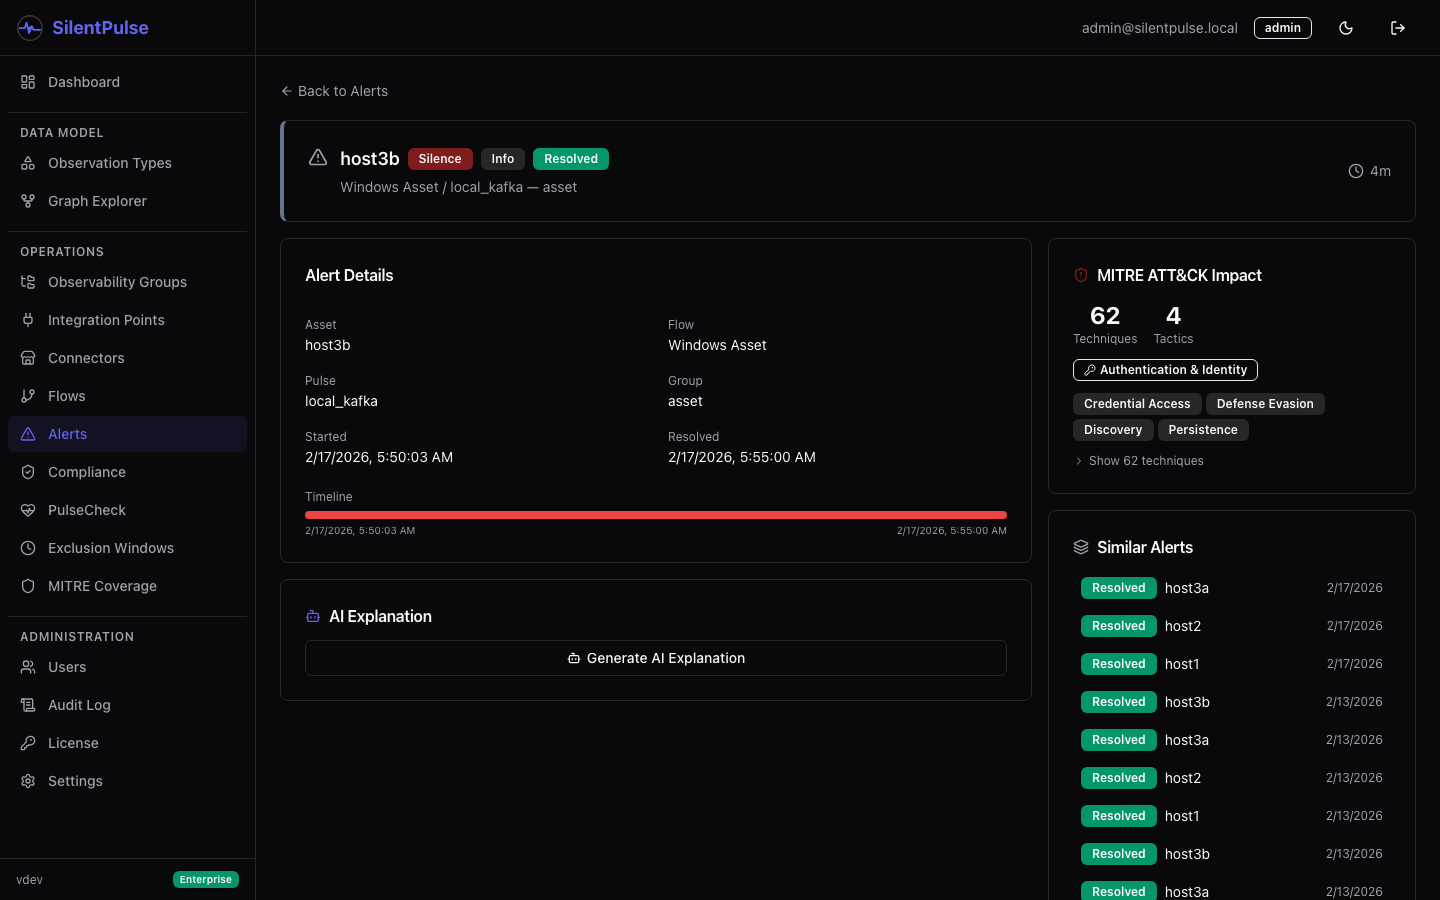
The similar alerts feature is new: SilentPulse automatically finds other alerts affecting the same asset or the same flow point. If DC-PROD-01 has been intermittently silent on Kafka over the past week, you’ll see those historical alerts immediately, no manual searching required.
What’s next: SilentPulse as an MCP server
The AI assistant we shipped today works inbound: you ask SilentPulse a question, it calls an LLM, you get an answer.
We’re already working on flipping that relationship. The next step is to expose SilentPulse as a Model Context Protocol (MCP) server, an open standard that allows any LLM or AI agent to query SilentPulse as a data source.
Consider a few scenarios:
A SOC analyst opens Claude or ChatGPT and asks: “Which assets in the finance department currently have telemetry gaps?” The model doesn’t hallucinate an answer. It queries SilentPulse in real time via MCP and returns actual, current data.
A SOAR playbook fires and needs to check: “Before I isolate this host, is telemetry flowing from it right now, or are we already blind?” It calls SilentPulse via MCP and makes an informed decision.
A detection engineer writing rules in VS Code asks their AI copilot: “Which MITRE techniques currently have coverage gaps in our environment?” The copilot pulls live coverage data from SilentPulse and suggests which detection rules to prioritize.
An automated triage agent enriches every incoming security incident with: “At the time of this alert, was the affected asset producing telemetry? Were we able to see this attack?”
This isn’t a hypothetical. MCP is an open specification with growing ecosystem support. The data SilentPulse holds (real-time telemetry health, MITRE coverage status, alert history, asset inventory) is exactly the kind of operational context that makes AI agents actually useful in security operations.
We’ve registered this as a feature on our roadmap. It’s coming.
The principle: AI as a tool, not a product
Every decision we make about AI in SilentPulse follows one principle: AI should be a tool that serves the analyst, not a product that replaces them.
We don’t gate features behind AI. Every alert, every MITRE mapping, every timeline visualization works without an LLM configured. The AI explanation is an enhancement, useful when you want it, invisible when you don’t.
We don’t lock you into our model. BYO LLM means you’re in control of the model, the infrastructure, the cost, and the data.
We don’t pretend AI is magic. The explanations are only as good as the context SilentPulse provides. That’s why we invested in rich alert data (security functions, MITRE mappings, flow stage context, asset traits) before adding AI on top. Garbage in, garbage out. Rich context in, actionable explanations out.
We don’t build AI features that can’t be explained. Every response shows which model generated it, whether it came from cache, and what data went into the prompt. Full transparency.
The security industry doesn’t need another AI startup. It needs tools that make analysts faster, more accurate, and less exhausted. That’s what we’re building.
SilentPulse is a security visibility monitoring system. The AI Assistant module is available now. Get started on GitHub or read the technical walkthrough to see SilentPulse in action.